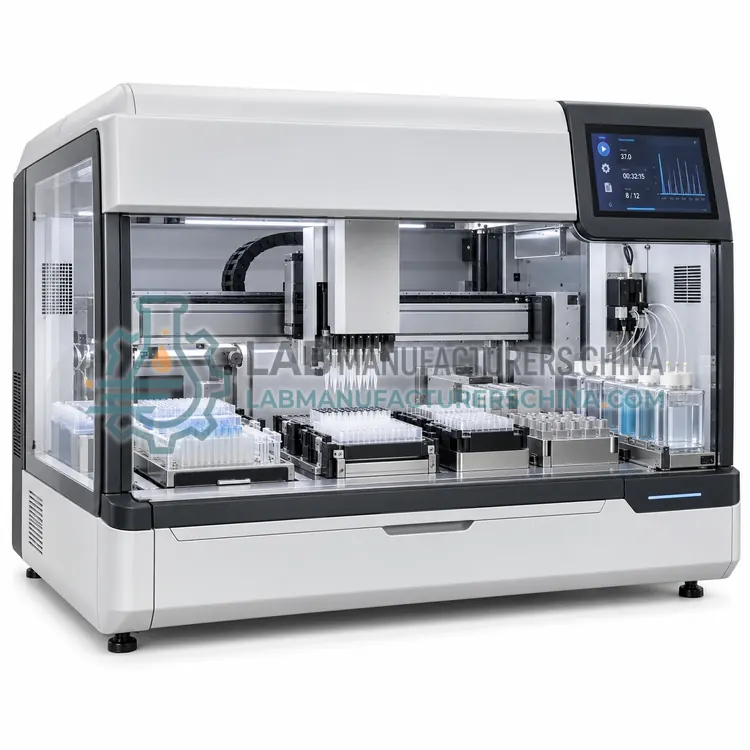
High-Throughput Production Sequencer
高通量生产型测序仪
- SKU DNS-0002
- DNA Sequencers
- CE (to be confirmed)
- ISO 9001 manufacturing (to be confirmed)
- IEC 61010-1 safety (to be confirmed)
- IEC 61326-1 EMC (to be confirmed)
Price on request — FOB / CIF quoted per order
Prices depend on configuration, quantity and destination port.
Key specifications
| Read length | 100–150 bp paired end (typical) |
|---|---|
| Output per run | 1–6 Tb |
| Reads per run | approx. 4–20 billion |
| Run time | approx. 1–4 days |
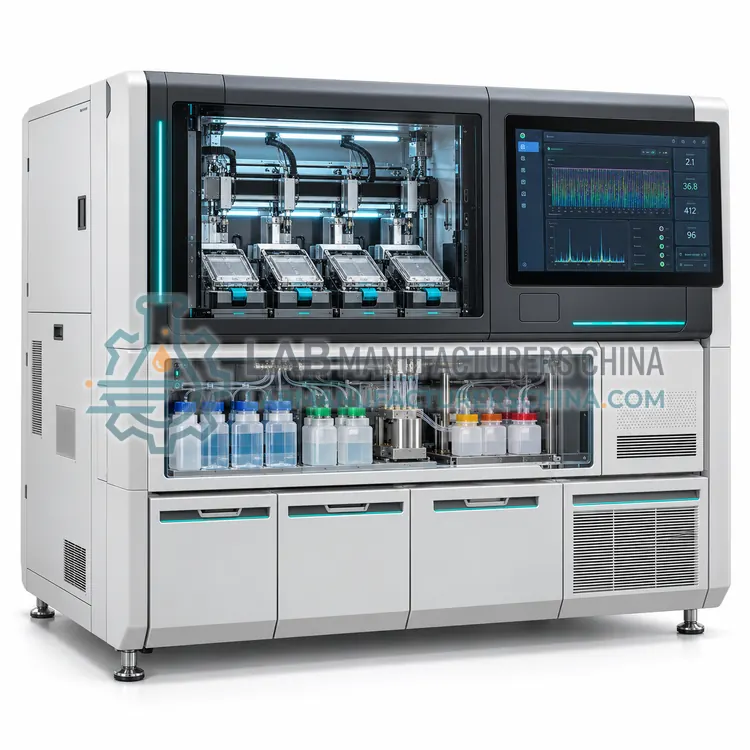
| Flow cells | 4 independently loaded flow cells |
| Raw accuracy | over 99% (typical) |
Request a quote Download brochure · to be provided
By Lab Manufacturers China Technical TeamLast reviewed Standards: ISO 20395, ISO 22174, ISO 15189
What is the High-Throughput Production Sequencer?
A high-throughput production sequencer delivers 1–6 Tb of short-read data per run across multiple flow cells, serving population genomics, large clinical cohorts and service laboratories that process hundreds of samples every week and need the lowest cost per gigabase.
Overview
Production sequencers scale the same sequencing-by-synthesis principle to multiple patterned flow cells loaded in parallel. A single run typically produces 1–6 Tb of 150-base paired reads, or roughly 4–20 billion reads, and runs for one to four days while the instrument processes flow cells independently so that new loads can start without waiting. Robotics or automated loaders handle flow cell and reagent replacement to limit operator involvement. On-board compute or a connected cluster performs base calling and demultiplexing, and data are streamed to network storage. Because cost per gigabase is the governing metric, laboratories usually pair these instruments with automated library preparation and pooled barcoding to keep the flow cell fully loaded. Typical installations include a controlled server room, uninterruptible power and a defined data retention policy.
How does it work?
Most high-throughput sequencers use sequencing by synthesis. A library of adapter-tagged fragments is loaded onto a flow cell or bead surface, where clonal clusters are formed so that each local signal comes from many identical copies. Fluorescently labelled nucleotides with reversible terminators are incorporated one base at a time by a polymerase; after each cycle the instrument images the surface, records the base colour for every cluster, and cleaves the terminator so the next base can be added. Base calls are assembled into reads and aligned to a reference. Nanopore instruments instead pull a single strand through a protein pore and read characteristic current changes for each base. Sanger instruments label fragments with chain-terminating dideoxy nucleotides and separate them by capillary electrophoresis with laser-induced fluorescence detection.
What are the key features?
- Output of 1–6 Tb per run across four independent flow cells
- Independent flow cell lanes allow flexible load scheduling
- Automated flow cell and reagent loading with run monitoring
- On-board base calling and demultiplexing with network data streaming
- Dual indexing supports thousands of multiplexed libraries per run
- Remote run monitoring with error and quality alerts
What are the technical specifications?
A typical high-throughput production sequencer configuration offers read length of 100–150 bp paired end (typical), output per run of 1–6 Tb, reads per run of approx. 4–20 billion, run time of approx. 1–4 days, flow cells of 4 independently loaded flow cells and raw accuracy of over 99% (typical). Values are indicative of the product class; the exact figures for each configuration are confirmed on the quotation and the calibration documents supplied with the instrument.
Which applications is it used for?
The High-Throughput Production Sequencer is used in population-scale whole-genome sequencing, large clinical cohort studies, high-throughput RNA sequencing projects and sequencing service providers and core facilities. Across the wider DNA Sequencers class, laboratories also deploy it for whole-genome and exome resequencing, RNA sequencing and gene expression profiling and pathogen whole-genome surveillance.
Which standards and certifications apply?
Relevant standards and methods include ISO 20395, ISO 22174, ISO 15189, CLSI MM09, IEC 61010-1 and ISO 17025. Certification candidates for this model are CE, ISO 9001 manufacturing, IEC 61010-1 safety and IEC 61326-1 EMC; each is to be confirmed for the specific configuration before shipment, and certificates are supplied only where they have been issued.
Sequencing instruments need a stable bench, clean power and a room with controlled temperature and low dust, because optics and flow-cell surfaces are sensitive. Illumina-style platforms are typically installed with their own compute server and require a defined data path, backup policy and firewall rules. Budget for consumables per run, flow-cell shelf life and the storage of large sequence files, which often exceeds instrument cost within a few years. Decontaminate the instrument area and use separate pre-PCR and post-PCR rooms to avoid amplicon carry-over. Validate accuracy and reproducibility with a reference genome or control library at installation and after major service. Sequence data from human samples must be handled under local privacy rules and, in clinical use, under ISO 15189 accreditation.
How do I select the right High-Throughput Production Sequencer?
Select a production sequencer only when sustained sample volume justifies it, since cost per gigabase falls sharply but capital, space and data infrastructure costs rise. Specify output per run, flow cell count, run time, loading automation, supported indexes, network bandwidth and the cost of a full flow cell run.
How does it compare with other DNA Sequencers variants?
Choose a sequencer by read length, output and accuracy rather than by headline specifications. For whole-genome resequencing, exomes, RNA sequencing and large amplicon panels, a benchtop short-read instrument with 15–150 Gb of output per run usually gives the lowest cost per sample and the simplest workflow. Production laboratories with many samples per week should compare cost per gigabase, run time and automated loading, and confirm whether indexes and flow cells are open or proprietary. Long-read platforms are decisive when repeats, structural variants, full-length transcripts or native DNA modifications matter. Keep a capillary sequencer for single-target confirmation, plasmid and amplicon checks where turnaround time dominates. Confirm the supported library kits, on-board or server analysis software, data storage and bioinformatics support before ordering.
Full specifications
| Read length | 100–150 bp paired end (typical) |
|---|---|
| Output per run | 1–6 Tb |
| Reads per run | approx. 4–20 billion |
| Run time | approx. 1–4 days |
| Flow cells | 4 independently loaded flow cells |
| Raw accuracy | over 99% (typical) |
| Samples per run | hundreds to thousands with indexing |
| Input DNA | 100 ng–1 µg (method dependent) |
| Data output | 10–100 GbE to network storage |
| Dimensions (W x D x H) | approx. 1,200 x 900 x 1,700 mm |
Indicative values for this product class. Final specifications are confirmed on the quotation and in the calibration documents supplied with the instrument.
Applications
- Population-scale whole-genome sequencing
- Large clinical cohort studies
- High-throughput RNA sequencing projects
- Sequencing service providers and core facilities
Key features
- Output of 1–6 Tb per run across four independent flow cells
- Independent flow cell lanes allow flexible load scheduling
- Automated flow cell and reagent loading with run monitoring
- On-board base calling and demultiplexing with network data streaming
- Dual indexing supports thousands of multiplexed libraries per run
- Remote run monitoring with error and quality alerts
Frequently asked questions about High-Throughput Production Sequencer
When a laboratory or service runs enough libraries to fill flow cells almost continuously, because unused capacity wastes the lower cost per gigabase. Weekly workloads of dozens of genomes, or large cohort projects with fixed deadlines, usually justify the higher capital and infrastructure cost.
Plan for 10 GbE or faster links to network storage, several hundred terabytes of capacity with a backup or archive tier, and compute for alignment and variant calling. A run of several terabases produces raw files that are large to transfer and expensive to keep indefinitely.
On most production instruments each flow cell is sequenced independently, so a new load can start while others are still running. This flexibility shortens turnaround for urgent samples and allows different read lengths or library types to be processed in parallel.
Short-read platforms read 75–300 bases per read with very high accuracy and low cost per base, which suits variant calling and expression profiling. Long-read platforms read thousands to millions of bases, resolving repeats and structural variants, but need more input DNA and cost more per base.
Requirements depend on the library method. Standard whole-genome libraries typically start from 100 ng to 1 µg of DNA, PCR-based amplicon methods need only 1–10 ng, and some tagmentation workflows accept as little as 10–50 ng. Degraded samples usually need more input.
Benchtop instruments often run base calling and secondary analysis on board or on a bundled computer, which is enough for small panels. Whole-genome or high-throughput work generally needs an external server or cluster for alignment, variant calling and storage of terabyte-scale data.
Related models