High-Throughput Library Preparation Platform
高通量文库制备平台
- SKU LPS-0002
- Library Preparation Systems
- CE (to be confirmed)
- ISO 9001 manufacturing (to be confirmed)
- IEC 61010-1 safety (to be confirmed)
Price on request — FOB / CIF quoted per order
Prices depend on configuration, quantity and destination port.
Key specifications
| Libraries per run | 96–384 |
|---|---|
| Libraries per working day | approx. 384–1,536 |
| Pipetting channels | 96 or 384 |
| Volume range | 1–1,000 µL |
| Pipetting accuracy | within ±2% at 200 µL (typical) |
| Plate formats | 96-well and 384-well |
Request a quote Download brochure · to be provided
By Lab Manufacturers China Technical TeamLast reviewed Standards: ISO 20395, ISO 15189, CLSI MM09
What is the High-Throughput Library Preparation Platform?
A high-throughput library preparation platform processes 96 to 384 libraries per run on a robotic deck with integrated normalisation, pooling and quality control, serving sequencing cores and service laboratories that need thousands of libraries per week at consistent quality.
Overview
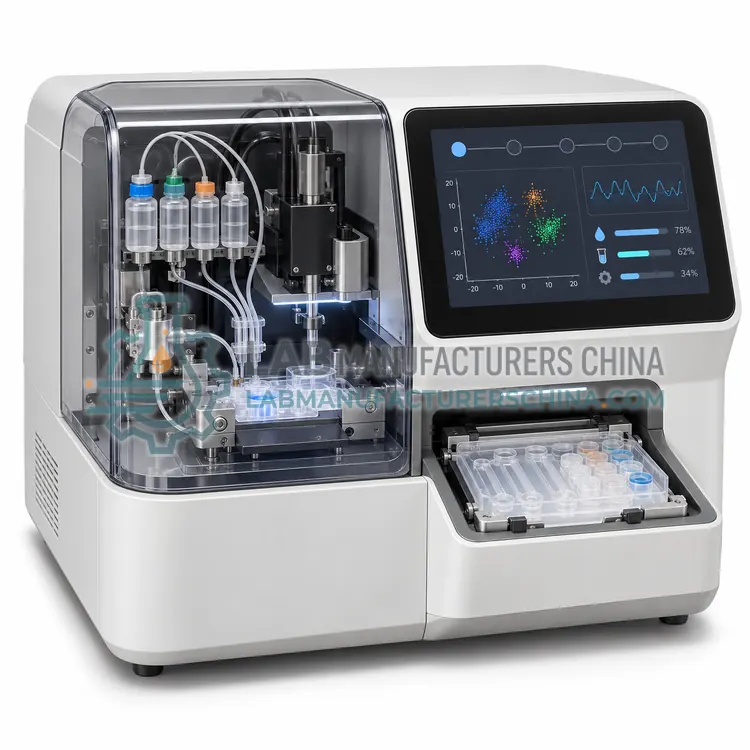
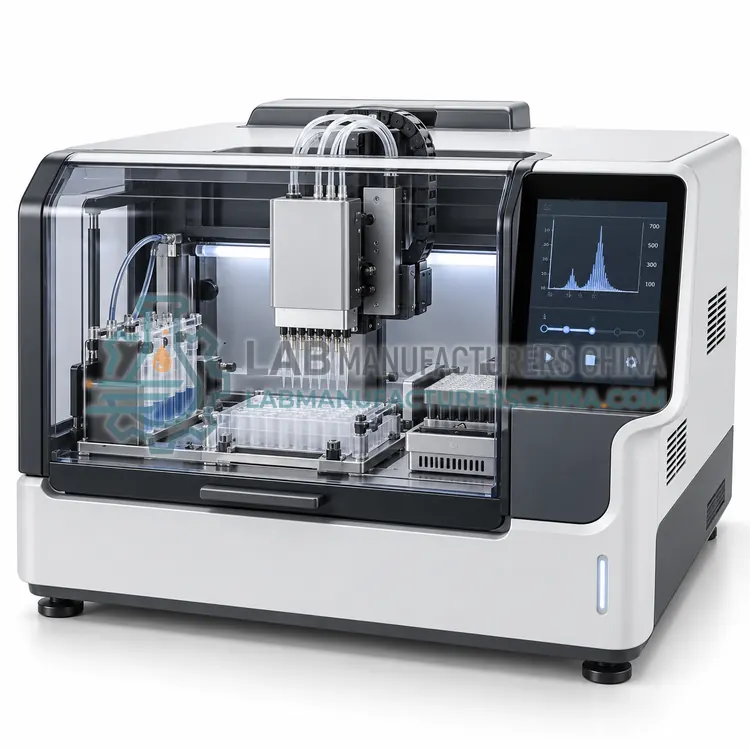
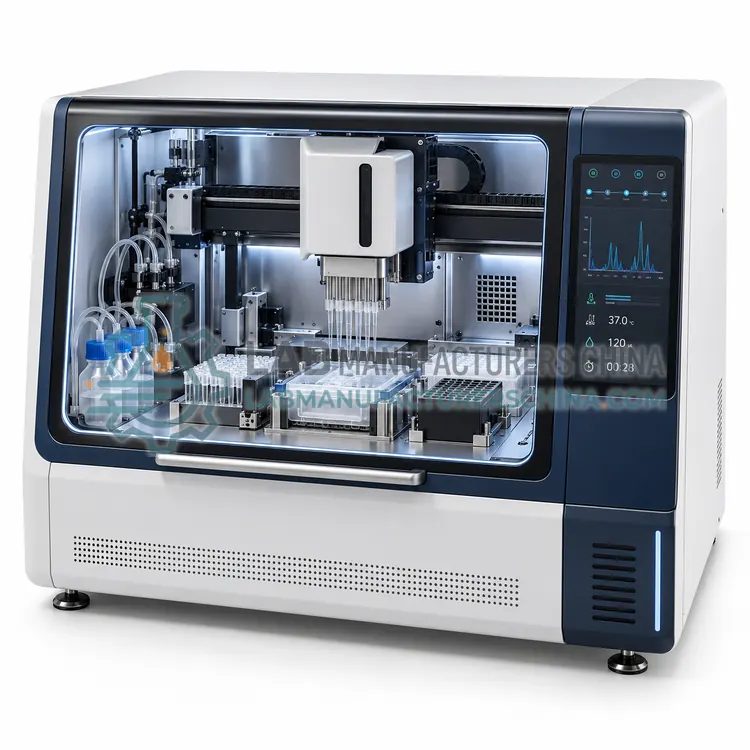
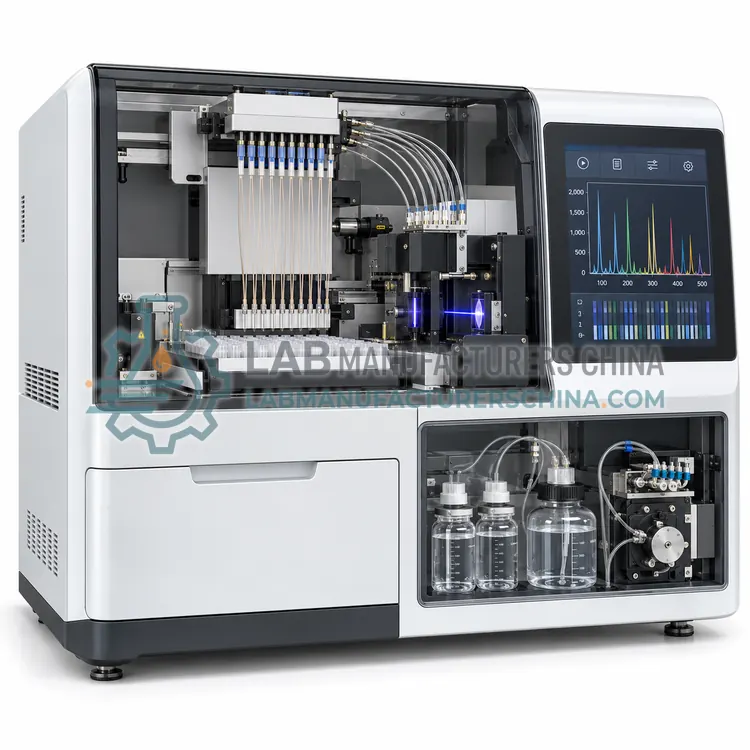
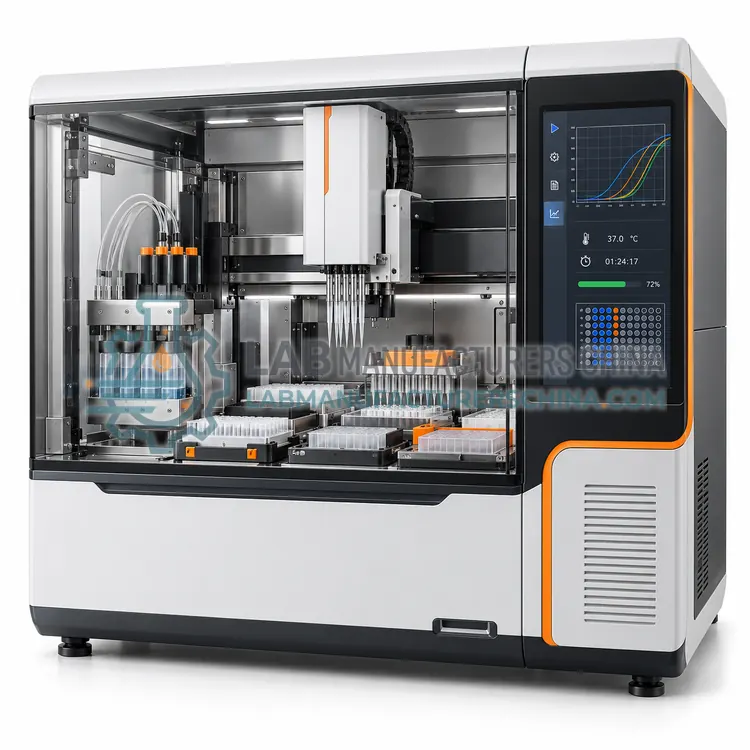
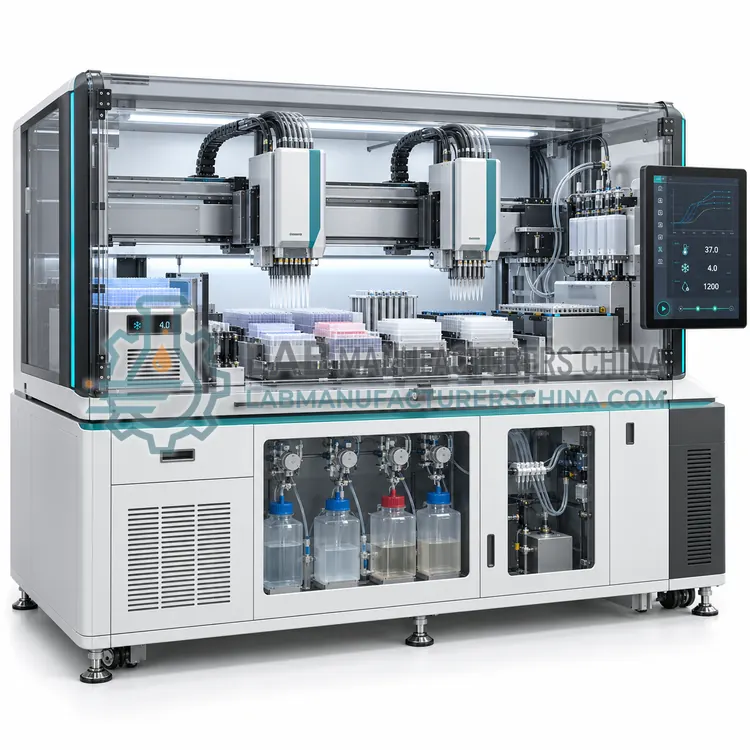
The platform combines a multi-channel pipetting head, magnetic modules, heating and cooling blocks, a thermocycler module and a plate hotel on one deck. Libraries are built in 96-well or 384-well plates, then quantified, normalised to a common concentration and pooled into a single tube for sequencing. Deck scheduling allows several plates to be processed in overlapping batches, so throughput reaches 384–1,536 libraries in a working day depending on protocol. Barcode reading at every transfer and LIMS connectivity keep library identity linked to sample records. Because the same deck performs cleanups, PCR and normalisation, consistency between plates is high, but protocols must be validated per kit and re-validated when reagents or plasticware change. Deck capacity, tip management and script validation effort are the practical limits.
How does it work?
A sequencing library is a pool of DNA fragments flanked by known adapter sequences that the sequencer recognises. Preparation starts with fragmentation by enzymatic digestion, tagmentation or sonication, which produces a defined size distribution. End repair and 3' adenylation make the ends ligatable, and adapters carrying sample indexes are attached by ligation or added during tagmentation. Size selection with magnetic beads or gel-free methods removes fragments outside the target window, and limited-cycle PCR enriches the library and completes the index sequences. Each step is separated by a magnetic bead cleanup that removes enzymes, salts and short fragments. For RNA libraries, reverse transcription and strand-specific second-strand synthesis precede the same workflow. Quality control after preparation measures concentration by fluorometry and fragment size distribution by capillary electrophoresis.
What are the key features?
- Robotic deck with 96 or 384-channel pipetting
- On-deck magnetic modules for cleanup and size selection
- Integrated normalisation and pooling into sequencing tubes
- Fluorometric quantification module for library yield
- Barcode reading and LIMS integration at every transfer
- Multiple plate scheduling with overlapping batches
What are the technical specifications?
A typical high-throughput library preparation platform configuration offers libraries per run of 96–384, libraries per working day of approx. 384–1,536, pipetting channels of 96 or 384, volume range of 1–1,000 µL, pipetting accuracy of within ±2% at 200 µL (typical) and plate formats of 96-well and 384-well. Values are indicative of the product class; the exact figures for each configuration are confirmed on the quotation and the calibration documents supplied with the instrument.
Which applications is it used for?
The High-Throughput Library Preparation Platform is used in sequencing core facility production workflows, population-scale whole-genome libraries, large RNA sequencing cohorts and diagnostic panels processed in high volume. Across the wider Library Preparation Systems class, laboratories also deploy it for whole-genome and exome library construction, RNA sequencing library preparation and single-cell and low-input library workflows.
Which standards and certifications apply?
Relevant standards and methods include ISO 20395, ISO 15189, CLSI MM09, IEC 61010-1 and ISO 17025. Certification candidates for this model are CE, ISO 9001 manufacturing and IEC 61010-1 safety; each is to be confirmed for the specific configuration before shipment, and certificates are supplied only where they have been issued.
Set up library preparation in a pre-PCR room separated from post-PCR and sequencing areas, and use dedicated pipettes, racks and reagents that never leave the room. Contamination from previous libraries shows up as unexpected index combinations, so include a no-template control in every batch and monitor index hopping between runs. Reagents are sensitive to freeze-thaw cycles, so aliquot enzymes and record lot numbers. Validate each new kit or automation script against a reference sample, checking yield, insert size and library complexity before routine use. Because library yield determines sequencing data quality, keep documentation that links each library to its sample, index, kit lot and operator so results can be traced during audits.
How do I select the right High-Throughput Library Preparation Platform?
Select a high-throughput platform when library batches regularly fill 96-well plates and normalisation or pooling has become a bottleneck. Specify deck capacity, channel count, supported kits, on-deck quantification, LIMS integration, tip consumption and the validation documentation provided for regulated use.
How does it compare with other Library Preparation Systems variants?
Begin with the sequencing platform and the input material. Short-read instruments need libraries with adapters matched to their flow cell chemistry, while long-read instruments need high molecular weight input and minimal PCR. Estimate the input amount per sample, because low-input and single-cell workflows require specialised chemistries. Then choose between manual kits for occasional use, magnetic bead automation for 8–96 samples per batch with walk-away operation, and full liquid-handling platforms for hundreds of samples with integrated normalisation and pooling. Check fragmentation method, index type and multiplexing level, size selection method, required equipment such as magnet racks or thermo mixers, and whether the supplier provides validated protocols for your sample type. Manual library preparation is a common source of batch effects, so automation usually pays back where sample numbers are high.
Full specifications
| Libraries per run | 96–384 |
|---|---|
| Libraries per working day | approx. 384–1,536 |
| Pipetting channels | 96 or 384 |
| Volume range | 1–1,000 µL |
| Pipetting accuracy | within ±2% at 200 µL (typical) |
| Plate formats | 96-well and 384-well |
| Input DNA | 10 ng–1 µg (kit dependent) |
| Quantification | On-deck fluorometric assay |
| Trackability | Barcode and LIMS-linked records with audit trail |
| Dimensions (W x D x H) | approx. 1,500 x 900 x 1,000 mm |
Indicative values for this product class. Final specifications are confirmed on the quotation and in the calibration documents supplied with the instrument.
Applications
- Sequencing core facility production workflows
- Population-scale whole-genome libraries
- Large RNA sequencing cohorts
- Diagnostic panels processed in high volume
Key features
- Robotic deck with 96 or 384-channel pipetting
- On-deck magnetic modules for cleanup and size selection
- Integrated normalisation and pooling into sequencing tubes
- Fluorometric quantification module for library yield
- Barcode reading and LIMS integration at every transfer
- Multiple plate scheduling with overlapping batches
Frequently asked questions about High-Throughput Library Preparation Platform
With overlapping plate scheduling, 384–1,536 libraries per working day are realistic, depending on protocol length and how much of the workflow, including normalisation and pooling, is automated. Sequencing capacity usually becomes the limiting factor.
Yes for normalisation purposes when the assay is calibrated with the same standards used on the bench and checked with control wells. For critical applications, laboratories still confirm final pool concentration on a separate instrument before loading.
At minimum, verify yield, insert size distribution, duplication rate and index balance on reference samples, then repeat once with a second operator and a second reagent lot. Records should state acceptance criteria and the version of the script used.
It converts nucleic acid into sequencer-ready fragments by fragmenting the DNA, repairing and adenylating ends, ligating indexed adapters, selecting a fragment size range and amplifying briefly. Each step is separated by a bead cleanup that removes enzymes and short fragments.
Standard libraries use 100 ng to 1 µg, tagmentation workflows accept 10–50 ng, and dedicated low-input or single-cell kits work from 1–10 ng or even picogram quantities. Lower input reduces library complexity and increases duplicate rates and PCR bias.
Insert size determines which reads map efficiently and how much of each fragment is sequenced. Selection removes adapter dimers and very short or very long fragments, improving alignment rates, reducing wasted reads and keeping library size distributions consistent between batches.
Related models